14Oct
EDGE AI · v4.2
SOC 2 · ISO 27001
INFERENCE AT THE EDGE
Deploy models to 312 edge regions
Vektor turns a trained model into a global, sub-50 ms API in one command. No clusters to babysit, no cold starts to apologise for.
// 01 — Platform
One runtime for every model
Bring a checkpoint, get an endpoint. Vektor compiles, shards and ships your model to the edge in the time it takes to push a commit.
Zero cold starts
Snapshots resume in 8 ms.
Multi-model graphs
Chain embeddings, rerankers and LLMs.
Live autoscaling
From zero to 40k RPS without a config change.
Confidential compute
Enclaves on every H100 node.
Vektor core
Compile
Kernel fusion and INT4 quantisation, per chip.
Distribute
Replicas pinned to 312 regions by demand.
Serve
Speculative decoding on every request.
Observe
Every token traced, every dollar counted.
Protect
Enclaves, audit logs and per-tenant keys.
vk init
Point at a checkpoint or a Hugging Face repo.
vk build
Compiled and quantised for every target chip.
vk deploy
Live in 312 regions in under a minute.
vk watch
Traces, costs and drift in one console.
// 02 — The lab
VK-X
A neural core that thinks in parallel
4.1 petaflops per rack.
SIGNAL_ACQUIRED::0xVK9
Built for impossible workloads.
Old way: cold starts — gone.
Latency you can actually feel
Keys that stay yours
 Edge mesh
↑ a different render on every visit
// 03 — Telemetry
Numbers that do not blink
Pulled live from the public status API. The chart below is last quarter; the clocks are where our on-call engineers are right now.
41 ms
p99 latency
312
edge regions
9,400 M
tokens / day
99.99%
uptime
Requests per second (thousands)
InferenceEmbeddings
Workload mix
LLMVisionSpeechOther
87%
GPU utilisation
Berlin
00:07:06
Tokyo
07:07:06
San Francisco
15:07:06
VK-X general availability in
67days
21hours
52min
53sec
// 04 — Media wall
See it, spin it, scrub it
Every way Marfilo can show a picture, a video or a sound — themed for a console.
 MeshRender
 ↔ Drag to spin the coreTensor cores2,048 INT4 units4.1 PFHBM3e192 GB at 8 TB/sNVLink bridge1.8 TB/s to the next card
Compute fabric
Every rack speaks to every other at 1.8 TB/s. Your model does not know where one GPU ends.
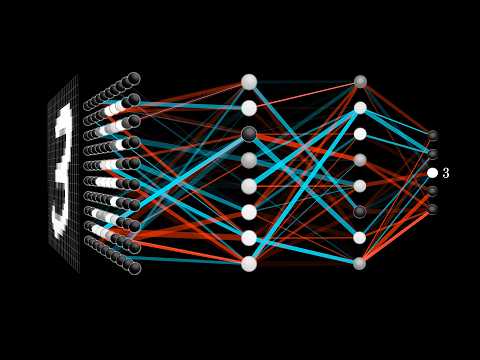
Boot chime — vk-sound-01.wav
Vektor Labs · Berlin, Kreuzberg
Keynote: intro to large language models — keeps playing in the corner when you scroll
// 05 — Developers
Three lines to production
The CLI, the SDK and the API speak the same language. Pick the one you like.
Deprecation
The v3 REST endpoints retire on 1 March 2027. The v4 SDK is a drop-in.
Install and deploy
bash
1$ curl -fsSL https://get.vektor.dev | sh
2$ vk login
3$ vk deploy ./llama-3-8b --regions all
4
5✔ compiled for H100, L4, MI300  (41s)
6✔ live in 312 regions
7→ https://llama-3-8b.vektor.run
Call it from anywhere
from vektor import Clientvk = Client()print(vk.chat("llama-3-8b", "Hello edge"))
import { Vektor } from "@vektor/sdk";const vk = new Vektor();await vk.chat("llama-3-8b", "Hello edge");
curl https://api.vektor.run/v4/chat \ -H "Authorization: Bearer $VK_KEY" \ -d '{"model":"llama-3-8b"}'
Limits and regions
| Model | Context | Tokens/s | Regions |
|---|---|---|---|
| llama-3-8b | 128k | 1,420 | 312 |
| mixtral-8x22b | 64k | 610 | 188 |
| vk-embed-2 | 8k | 48,000 | 312 |
| whisper-large-v4 | — | 90× realtime | 140 |
Nothing matches your search.
Questions engineers ask
Can I bring my own GPUs?
Yes. Install the vk-agent on any node with a supported card and it joins your private region.
What happens during a region outage?
Traffic fails over to the next-closest warm replica in under 200 ms.
Do you train on my data?
Never. Prompts and completions are not stored unless you turn on tracing.
Show the full changelog for v4.2
Speculative decoding on by default · INT4 for MI300 · 38% faster snapshot restore · new São Paulo and Lagos regions.
// 06 — Journal
Notes from the lab
Straight from the blog — this carousel is the Post list module, filling one card design with every post.
No lab notes yet.
// 07 — Pricing
Pay per token. Nothing else.
Start free, scale without talking to sales. Switch billing below.
2 months free
| Hobby | Best valueScale | Enterprise | |
|---|---|---|---|
| Edge regions | 3 | 312 | 312 + private |
| Private models | |||
| Confidential compute | |||
| SSO & audit logs | |||
| Support | Community | 24/7 on-call |
Store
Credit packs
Starter pack$9
10M tokens, never expire
Builder packHot$79
100M tokens + priority queue
GPU-hour bundle$149
50 H100 hours for fine-tuning
SOC 2 Type II
Audited yearly
Encrypted
AES-256 at rest
EU residency
Frankfurt + Paris
99.99% SLA
Or credits back
Account
Console sign-in
Login
Your stack is empty — add a credit pack.
// 08 — Crew
Built by people who hate latency
Ex-compiler engineers, SREs and one very patient physicist.
Ada Lindqvist
CEO · ex-XLA compiler
Shipped the first INT4 kernel that nobody could tell apart from FP16.
Kai Okafor
CTO · distributed systems
Believes every millisecond is a bug report nobody filed yet.
Noor Rahman
Head of research
Physicist turned scheduler whisperer. Owns the orbital planner.
★★★★★★★★★★We moved 40 models off our own cluster in a weekend. p99 dropped from 380 ms to 44.
The edge is not a place. It is a latency budget.
★★★★★★★★★★Cold starts were our number one support ticket. They are gone.
★★★★★★★★★★The console is the first ML dashboard my finance team understands.
★★★★★★★★★★We deploy to 180 regions from a GitHub Action. That is the whole pipeline.
Kernel fusion
Hover to see the trick.
3.2× fewer launches
Adjacent ops become one kernel.
Weight streaming
Hover to see the trick.
8 ms resumes
Weights stream from NVMe as layers run.
Speculative decode
Hover to see the trick.
2.4× tokens/s
A draft model guesses, the big one checks.
Changelog of a company
2023
fork()
Three compiler engineers leave a big lab.
2024
First edge region
Frankfurt. One rack. 11 customers.
2025
Series B
$120M to put a GPU near everyone.
2026
VK-X
Our own neural core, fabbed at 3 nm.
// 09 — Contact
Open a channel
Tell us what you are running. An engineer — not a salesperson — answers within one working day.
Prefer a terminal?
Open a ticket straight from the CLI with vk support new, or write to hello@vektor.dev.
- Status: all systems nominal
- Security: security@vektor.dev (PGP)
<!-- status: 200 OK · rendered by the HTML module -->
Ship your first model before the coffee cools
Free tier, no card, 312 regions. The CLI installs in four seconds.
Every block on this page is a Marfilo module.
108 of them, one document, served as static HTML.
© 2023–2026 Vektor Labs GmbH — a fictional company, built as a Marfilo demo.